 Rustango
Caching
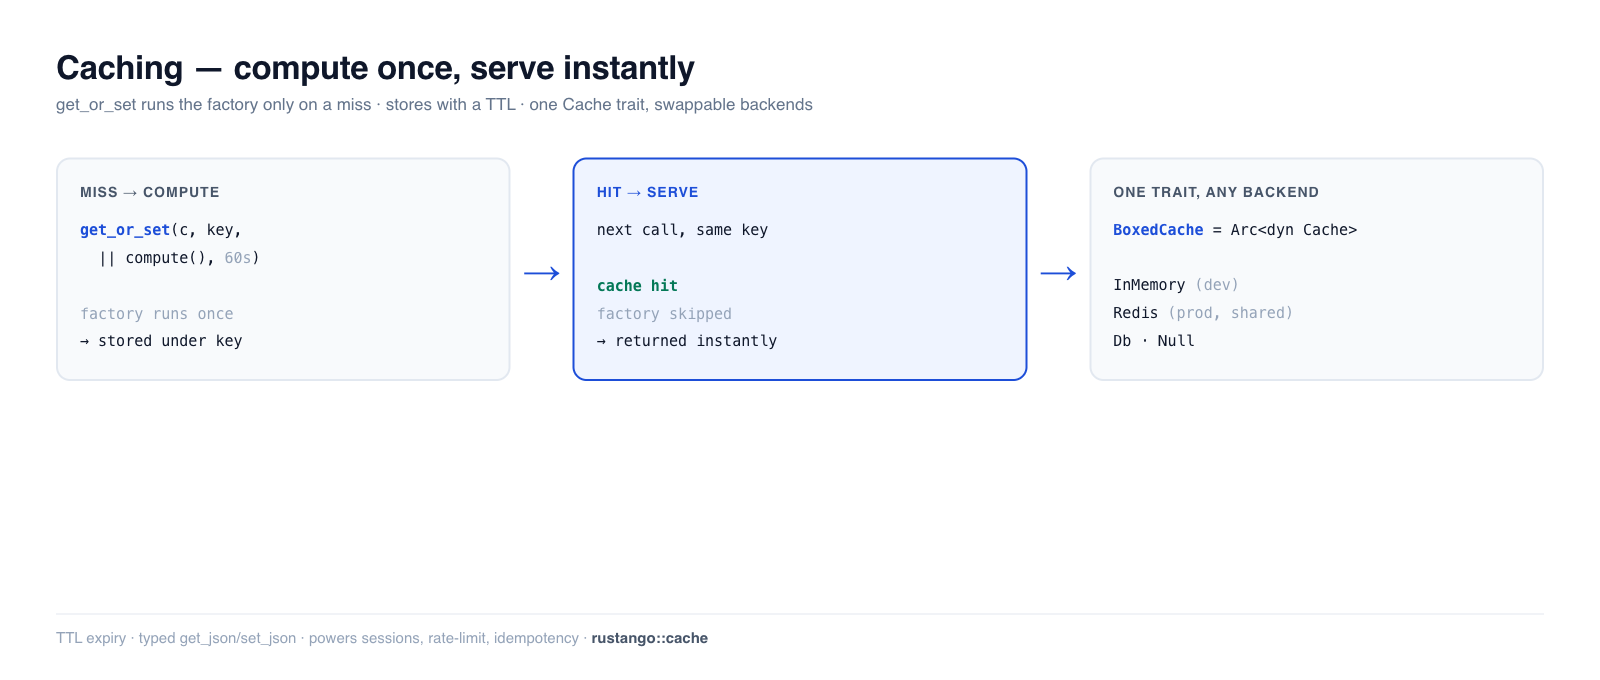
Caching stores the result of expensive work — a heavy query, a rendered
fragment, a third-party API call — so the next request gets it instantly instead
of recomputing. Rustango gives you one Cache trait with swappable backends
(in-memory, Redis, database), a compute-on-miss helper (get_or_set), and typed
JSON helpers. Swap the backend without touching a single call site — like
Django's cache framework or Laravel's Cache facade.
New to a term here? cache, TTL, key, backend — see the glossary.
Source:
rustango::cache(Cache,InMemoryCache,NullCache,get_or_set,get_json,set_json,BoxedCache,from_settings) — behind thecachefeature (on by default).RedisCacheneeds thecache-redisfeature (off by default).Runnable version: every snippet is copied from
cache_doc.rs(cargo test -p rustango --test cache_doc); the database backend is dogfooded on SQLite bycache_db_backend_sqlite_live.rs.
Table of contents
- Step 1 — Pick a backend
- Step 2 — get / set / delete
- Step 3 — get_or_set (cache-aside)
- Typed JSON values
- TTL and expiry
- Swapping backends
- Caching under multi-tenancy
- Reference
- See also
Step 1 — Pick a backend
Every backend implements the same Cache trait, so your code is identical
whichever you choose. App code holds a BoxedCache (Arc<dyn Cache>) and
never names the concrete type:
use rustango::cache::{BoxedCache, InMemoryCache};
use std::sync::Arc;

let cache: BoxedCache = Arc::new(InMemoryCache::new());
| Backend | Feature | Use for |
|---|---|---|
InMemoryCache | cache | dev, tests, single process (per-process HashMap + TTL) |
RedisCache | cache-redis | production; shared across replicas |
DbCache | cache | production without Redis; a rustango_cache table |
NullCache | cache | disable caching (every read misses) — handy in tests |
Step 2 — get / set / delete
The core of the trait is four async methods. set takes an optional TTL
(None = no expiry); get returns Option<String> (None on a miss):
use rustango::cache::{Cache, InMemoryCache};

let cache = InMemoryCache::new();

assert_eq!(cache.get("greeting").await?, None);     // miss
cache.set("greeting", "hello", None).await?;        // store, no expiry
assert_eq!(cache.get("greeting").await?.as_deref(), Some("hello"));
assert!(cache.exists("greeting").await?);

cache.delete("greeting").await?;                    // gone
There are batch variants too — get_many / set_many / delete_many.
Step 3 — get_or_set (cache-aside)
This is the one you'll reach for most. get_or_set returns the cached value, or
— on a miss — runs your factory, stores the result with a TTL, and returns it.
The factory only runs on a miss:
use rustango::cache::get_or_set;
use std::time::Duration;

let stats: HomeStats = get_or_set(
    &*cache,                       // &dyn Cache
    "home:stats",
    || async { compute_home_stats(&pool).await },   // runs only on a miss
    Some(Duration::from_secs(60)),                   // cache for 60s
).await?;
The backing test calls get_or_set twice for the same key and asserts the
factory ran exactly once — the second call is served from the cache.
Invalidate on write. Cache-aside means stale data until the TTL expires. For data that changes, also
delete(key)when you write it — e.g. from apost_savesignal — so the next read recomputes.
Typed JSON values
get_json / set_json serialize any Serialize/Deserialize type to JSON, so
you cache structs and lists, not just strings:
use rustango::cache::{get_json, set_json};

#[derive(serde::Serialize, serde::Deserialize)]
struct Profile { id: i64, name: String }

set_json(&*cache, "profile:7", &profile, None).await?;
let back: Option<Profile> = get_json(&*cache, "profile:7").await?;   // None on a miss
(get_or_set uses these under the hood, which is why its value type must be
Serialize + Deserialize.)
TTL and expiry
Pass a Duration to set (or get_or_set) and the entry disappears after it.
Verified: a 50 ms entry is readable immediately and gone after 80 ms.
cache.set("flash", "x", Some(Duration::from_millis(50))).await?;
// ...50ms later...
assert_eq!(cache.get("flash").await?, None);   // expired
InMemoryCache::with_default_ttl(d) sets a default TTL applied when you pass
None.
Swapping backends
Because everything is the Cache trait, switching from in-memory to Redis is a
one-line change at startup — usually driven by config so it differs per
environment:
// Build the cache from `[cache]` settings (backend = "memory" | "redis" | "db" | "null").
let cache: BoxedCache = rustango::cache::from_settings(&settings.cache);
In production, point it at Redis (shared across all your replicas):
use rustango::cache::RedisCache;   // needs the `cache-redis` feature
let cache: BoxedCache = std::sync::Arc::new(RedisCache::new("redis://localhost").await?);
Same get / set / get_or_set calls — only the constructor changed.
Caching under multi-tenancy
Cache is a flat &str-keyed store, which under tenancy makes the natural
key the leaky key: a handler — or worse a background task, which has no
ambient tenant to borrow from — writes "stats:monthly" for one tenant and
every other tenant reads it back.
Wrap the shared cache in a ScopedCache so the namespace is applied for
you and the call site cannot forget:
use rustango::cache::ScopedCache;

// From the Org the resolver already produced:
let cache = ScopedCache::for_tenant(shared.clone(), &t.org.slug);

cache.set("stats:monthly", &json, ttl).await?;   // stored as tenant:acme:stats:monthly
cache.get("stats:monthly").await?;               // reads only acme's entry
cache.clear().await?;                            // drops ONLY acme's entries
ScopedCache is itself a Cache, so it drops into anything taking a
BoxedCache — cache_page, cache_fragment, the rate limiters,
DistributedLock. It forwards to the inner backend with mapped keys rather
than reimplementing anything, so native primitives (Redis INCRBY, SET NX,
MGET) keep their atomicity and batching.
Atomic counters and locks. Cache::incr backs rate limiting
and per-account lockout; Cache::add (set-if-absent) backs DistributedLock.
Both are atomic on RedisCache (native INCRBY / SET NX) and on
InMemoryCache (which holds its lock across the read-modify-write);
DatabaseCache leaves both at the non-atomic default — fine for one process,
but reach for Redis when a counter or lock must be exact across replicas.
Two things worth knowing:
| It is a namespace, not a boundary | Everything still lives in one backend, and code holding the unscoped cache can read any key. The point is that the ergonomic path is the correct one. |
clear() needs key enumeration | It routes through Cache::delete_prefix. InMemoryCache filters its map and DatabaseCache issues a DELETE … LIKE 'prefix%'. A backend that cannot enumerate — FileCache hashes keys into paths — falls back to clearing everything and logs a warning. That is deliberate: under-deleting would let another namespace read a stale entry, which is a correctness bug, while over-deleting only costs a cache miss. |
The unscoped Cache::clear() is still process-global, so reach for the scoped
view whenever a single tenant's change is what triggered the invalidation.
Reference
Cache trait: get · set(key, value, ttl) · delete · exists ·
get_many / set_many / delete_many · get_or(key, default).
Free helpers: get_or_set(cache, key, factory, ttl) ·
get_json / set_json · from_settings(&CacheSettings).
What's built on the cache: server-side sessions,
distributed rate limiting (CacheRateLimitLayer), idempotency
keys, and feature flags all take a BoxedCache — so one Redis instance backs
all of them.
See also
- Background jobs — the other half of keeping requests fast (defer work instead of caching its result).
- Sessions — a server-side store built on
Cache. - Middleware —
CacheRateLimitLayershares a counter across replicas via the cache. - ORM cookbook — invalidate cached reads from a
post_savesignal.