 Rustango
Caching
Caching stores the result of expensive work — a heavy query, a rendered
fragment, a third-party API call — so the next request gets it instantly instead
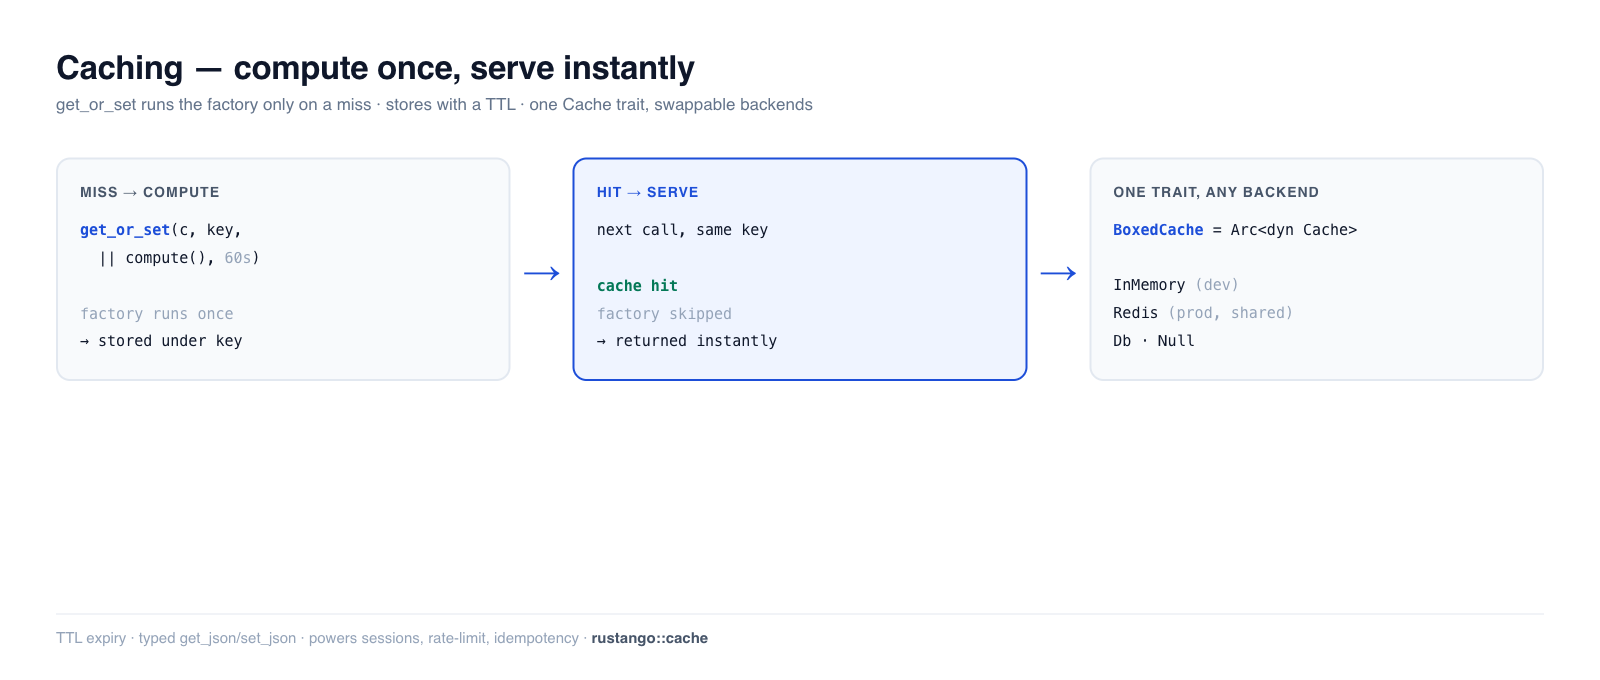
of recomputing. Rustango gives you one Cache trait with swappable backends
(in-memory, Redis, database), a compute-on-miss helper (get_or_set), and typed
JSON helpers. Swap the backend without touching a single call site.
New to a term here? cache, TTL, key, backend — see the glossary.
Source:
rustango::cache(Cache,InMemoryCache,NullCache,get_or_set,get_json,set_json,BoxedCache,from_settings) — behind thecachefeature (on by default).RedisCacheneeds thecache-redisfeature (off by default).Runnable version: every snippet is copied from
cache_doc.rs(cargo test -p rustango --test cache_doc); the database backend is dogfooded on SQLite bycache_db_backend_sqlite_live.rs.
Table of contents
- Step 1 — Pick a backend
- Step 2 — get / set / delete
- Step 3 — get_or_set (cache-aside)
- Typed JSON values
- TTL and expiry
- Swapping backends
- Caching under multi-tenancy
- Caching whole pages
- Reference
- See also
Step 1 — Pick a backend
Every backend implements the same Cache trait, so your code is identical
whichever you choose. App code holds a BoxedCache (Arc<dyn Cache>) and
never names the concrete type:
use rustango::cache::{BoxedCache, InMemoryCache};
use std::sync::Arc;

let cache: BoxedCache = Arc::new(InMemoryCache::new());
| Backend | Feature | [cache] backend | Use for |
|---|---|---|---|
InMemoryCache | cache | memory (default) | dev, tests, single process (per-process HashMap + TTL) |
RedisCache | cache-redis | redis | production; shared across replicas |
DatabaseCache | cache | db / database | production without Redis; a rustango_cache table |
FileCache | cache | file | one file per key under file_cache_dir; shared only if the directory is |
NullCache | cache | null / none | disable caching (every read misses) — handy in tests |
There is no postgres value — the DB backend is db or database. Values
are lowercase. An unknown or mis-cased value (Redis, a typo), or file
without file_cache_dir, logs an error and falls back to an in-memory cache;
a later minor release will refuse it.
FileCache sweeps one sixteenth of its directory for expired entries every 16
writes. Call FileCache::purge_expired() on a schedule to sweep it all. New
directories are created 0700 and entries 0600 on Unix.
Step 2 — get / set / delete
The core of the trait is four async methods. set takes an optional TTL
(None = no expiry); get returns Option<String> (None on a miss):
use rustango::cache::{Cache, InMemoryCache};

let cache = InMemoryCache::new();

assert_eq!(cache.get("greeting").await?, None);     // miss
cache.set("greeting", "hello", None).await?;        // store, no expiry
assert_eq!(cache.get("greeting").await?.as_deref(), Some("hello"));
assert!(cache.exists("greeting").await?);

cache.delete("greeting").await?;                    // gone
There are batch variants too — get_many / set_many / delete_many.
Step 3 — get_or_set (cache-aside)
This is the one you'll reach for most. get_or_set returns the cached value, or
— on a miss — runs your factory, stores the result with a TTL, and returns it.
The factory only runs on a miss:
use rustango::cache::get_or_set;
use std::time::Duration;

let stats: HomeStats = get_or_set(
    &*cache,                       // &dyn Cache
    "home:stats",
    || async { compute_home_stats(&pool).await },   // runs only on a miss
    Some(Duration::from_secs(60)),                   // cache for 60s
).await?;
The backing test calls get_or_set twice for the same key and asserts the
factory ran exactly once — the second call is served from the cache.
Invalidate on write. Cache-aside means stale data until the TTL expires. For data that changes, also
delete(key)when you write it — e.g. from apost_savesignal you send after the save (saving does not send it) — so the next read recomputes.
Typed JSON values
get_json / set_json serialize any Serialize/Deserialize type to JSON, so
you cache structs and lists, not just strings:
use rustango::cache::{get_json, set_json};

#[derive(serde::Serialize, serde::Deserialize)]
struct Profile { id: i64, name: String }

set_json(&*cache, "profile:7", &profile, None).await?;
let back: Option<Profile> = get_json(&*cache, "profile:7").await?;   // None on a miss
(get_or_set uses these under the hood, which is why its value type must be
Serialize + Deserialize.)
TTL and expiry
Pass a Duration to set (or get_or_set) and the entry disappears after it.
Verified: a 50 ms entry is readable immediately and gone after 80 ms.
cache.set("flash", "x", Some(Duration::from_millis(50))).await?;
// ...50ms later...
assert_eq!(cache.get("flash").await?, None);   // expired
InMemoryCache::with_default_ttl(d) sets a default TTL applied when you pass
None.
A TTL is an upper bound, not a guarantee
InMemoryCache is size-bounded by default — 256 MiB or 100 000 entries,
whichever it hits first — with approximate-LRU eviction. A flood of unique keys
cannot grow the process without limit, but it does mean an entry can vanish
before its TTL expires if it is the least recently used when the budget is
reached. Eviction drops already-expired entries first, then the least-recently
used, until both are 10% under budget. Entries written with set_forever
(feature flags) are outside the budgets and never evicted while they stay within
their own caps — 16 MiB or 10 000 entries (.with_max_pinned_bytes(..) /
.with_max_pinned_entries(..)). Past those, new set_forever entries are stored
as ordinary, evictable entries and a warning is logged once.
So treat a cache read as "may be absent" even inside the TTL. That is true of every cache backend, but here it has a cause you can reason about and tune:
InMemoryCache::new()
    .with_max_bytes(512 * 1024 * 1024)   // raise the budget
    .with_max_entries(0)                 // 0 = unbounded (pre-bounding behaviour)
TTL itself is enforced lazily, on read — there is no background eviction thread, so an expired entry still occupies its slot until something asks for it or eviction reaches it.
Swapping backends
Because everything is the Cache trait, switching from in-memory to Redis is a
one-line change at startup — usually driven by config so it differs per
environment:
// Build the cache from `[cache]` settings. `from_settings_async` is the one
// to reach for — it can build the backends that need to connect.
let cache: BoxedCache = rustango::cache::from_settings_async(&settings.cache).await?;
backend | from_settings (sync) | from_settings_async |
|---|---|---|
memory, null, file | ✓ | ✓ |
redis | panics — cannot be built synchronously | ✓ |
db | panics — needs a runtime &Pool | error; build it where the pool is |
The sync resolver panics rather than substituting a backend.
It used to warn and
return an in-memory cache, which is not a degraded shared cache — it is a
different one. A per-process cache multiplies CacheRateLimitLayer's limit by
the replica count, and stops verify_single_use failing closed, so the same
reset link works once per replica. Both of those are documented as working
because the cache is shared, and a warning at boot does not reach whoever
debugs that a week later.
db cannot come from [cache] at all, because DatabaseCache needs a pool
that settings do not carry:
let cache = DatabaseCache::new(pool.clone(), "rustango_cache");
cache.ensure_table().await?;
let boxed: BoxedCache = std::sync::Arc::new(cache);
In production, point it at Redis (shared across all your replicas):
use rustango::cache::RedisCache;   // needs the `cache-redis` feature
let cache: BoxedCache = std::sync::Arc::new(RedisCache::new("redis://localhost").await?);
Same get / set / get_or_set calls — only the constructor changed.
Caching under multi-tenancy
Cache is a flat &str-keyed store, which under tenancy makes the natural
key the leaky key: a handler — or worse a background task, which has no
ambient tenant to borrow from — writes "stats:monthly" for one tenant and
every other tenant reads it back.
Wrap the shared cache in a ScopedCache so the namespace is applied for
you and the call site cannot forget:
use rustango::cache::ScopedCache;

// From the Org the resolver already produced:
let tenant = TenantSlug::of(&t.org).expect("a registry org");
let cache = ScopedCache::for_tenant(shared.clone(), &tenant);

cache.set("stats:monthly", &json, ttl).await?;   // stored as tenant:#org:7:acme:stats:monthly
cache.get("stats:monthly").await?;               // reads only acme's entry
cache.clear().await?;                            // drops ONLY acme's entries
ScopedCache is itself a Cache, so it drops into anything taking a
BoxedCache — cache_page, cache_fragment, the rate limiters,
DistributedLock. It forwards to the inner backend with mapped keys rather
than reimplementing anything, so native primitives (Redis INCRBY, SET NX)
keep their atomicity. get_many / set_many / delete_many forward too, but no
shipped backend batches them yet: each is one round trip per key.
Atomic counters and locks. Cache::incr backs rate limiting
and per-account lockout; Cache::add (set-if-absent) backs DistributedLock.
Cache::add is atomic on all three — RedisCache (SET NX), InMemoryCache
(which holds its lock across the read-modify-write) and DatabaseCache, which
does the test-and-set under row locks so a race resolves to exactly one winner.
Cache::incr is atomic on all three too: DatabaseCache does it in one upsert.
FileCache does both under a per-entry lock, which holds only on one host.
So a DistributedLock or an exact counter works across replicas on Redis or
the database. Every backend counts over the full i64 range; an overflow is
an error and leaves the counter as it was.
A stored value counts only in the exact form incr writes ("7", "-3");
"+7", "007", " 5" or "abc" count as 0 everywhere. A text value with a
NUL character is refused on every backend; store such data with set_bytes.
Two things worth knowing:
| It is a namespace, not a boundary | Everything still lives in one backend, and code holding the unscoped cache can read any key. The point is that the ergonomic path is the correct one. |
clear() needs key enumeration | It routes through Cache::delete_prefix, and every built-in backend implements it: InMemoryCache filters its map, DatabaseCache issues DELETE … LIKE 'prefix%' with %, _ and the escape character themselves escaped, RedisCache uses SCAN+MATCH with glob metacharacters escaped, and FileCache scans its directory and matches the key stored in each entry. A backend that does not implement it now gets an error rather than a fallback. DatabaseCache stores keys over 255 bytes hashed and matches a prefix over 190 bytes on its first 190 bytes, so it may delete extra keys, never fewer. |
The unscoped Cache::clear() is still process-global, so reach for the scoped
view whenever a single tenant's change is what triggered the invalidation.
A purged tenant's slug can be reused by a new tenant. To make purge-tenant
delete the old tenant's ScopedCache::for_tenant keys, call
rustango::tenancy::decommission::clear_on_purge(cache) at boot for each cache
that holds them.
Caching whole pages
CachePageLayer::new(cache) (in rustango::cache_page) stores GET responses
in any BoxedCache; .timeout(dur) sets how long (default 60 s). It is safe
by default:
- A request with
Authorization,CookieorX-Api-Keyis neither served from nor stored in the cache. Name more credential headers (a custom token header) with.credential_headers(["x-my-token"])..cache_authenticated(true)turns this off, only for a route whose page is the same for every caller. - A response with
Set-Cookie, orCache-Control: private,no-cacheorno-store, is never cached. .vary_on([...])puts request headers in the key.- The raw query string is in the key by default, so each distinct query stores
its own entry and
?x=<random>can fill the cache..query_keys(["page", "q"])keys only on those params, sorted;.ignore_query()leaves the query out. .key_prefix(..)gives each layer its own keyspace (defaultrustango.cache_page)..cache_query(true)also cachesQUERYrequests, keyed on a digest of the body (up to 1 MiB)..tenant_agnostic(true)caches without a resolved tenant, only for a page that is the same for every tenant.
To drop a page after a write, call
layer.invalidate(&[PageKey::new(path, host)]).await? on a clone of the layer
(add .tenant(org_id) to the key under tenancy). It purges every cached variant
of that path: any query string, any vary_on value, GET and QUERY alike. It
works through a per-path generation counter, so each cached GET reads one more
small cache key.
Under tenancy, mount the layer inside the tenancy layer; see Middleware.
Reference
Cache trait: get · set(key, value, ttl) · set_forever · delete ·
exists / has_key · clear · delete_prefix · incr / decr · add
(set-if-absent) · touch (new TTL) · get_bytes / set_bytes ·
get_many / set_many / delete_many · get_or(key, default).
Free helpers: get_or_set(cache, key, factory, ttl) ·
get_json / set_json · from_settings(&CacheSettings) ·
from_settings_async(&CacheSettings).
Housekeeping: DatabaseCache::purge_expired() and
FileCache::purge_expired() delete expired entries; call them on a schedule.
What's built on the cache: server-side sessions,
distributed rate limiting (CacheRateLimitLayer), idempotency
keys, and feature flags all take a BoxedCache — so one Redis instance backs
all of them.
See also
- Background jobs — the other half of keeping requests fast (defer work instead of caching its result).
- Sessions — a server-side store built on
Cache. - Middleware —
CacheRateLimitLayershares a counter across replicas via the cache. - ORM cookbook — invalidate cached reads from a
post_savesignal.